ChatGPT cites a page when two separate things have happened: its search layer retrieved the page for a query it issued on your behalf, and the answer being written needed evidence that page carried in liftable form. Most advice collapses the two, which is why rewriting a page you own rarely moves anything. Across 602 controlled prompts and 21,143 search-layer citations, ChatGPT cited fewer sources per answer than Google or Perplexity while showing substantially higher average citation influence among the pages it fetched.1
Key takeaways
Gate one is access, settled in robots.txt: sites opted out of OAI-SearchBot “will not be shown in ChatGPT search answers”.
Gate two is absorption. ChatGPT gives fewer citation slots per answer than Perplexity or Google, so each one is scarcer.
High-influence pages measure out longer, more structured, and rich in definitions, facts, comparisons and steps.
Reddit’s share of ChatGPT citations was published as 16.8%, 12.6%, 3.11% and 0.52% in eleven months, each with a different denominator.
Editing the page you own keeps testing null: 54 cases, three statistically significant.
The two gates
Why does ChatGPT cite some sources and ignore others?
Because two systems have to say yes and they judge different things. OpenAI runs a separate crawler for each job, and only one governs search: “Sites that are opted out of OAI-SearchBot will not be shown in ChatGPT search answers, though can still appear as navigational links.” The same page adds that “ChatGPT-User is not used to determine whether content may appear in Search”, and GPTBot is for model training.5 Gate one is binary and settled in robots.txt.
Gate two is different in kind. The framework behind the largest public citation dataset splits the problem into citation selection, where a platform picks sources, and citation absorption, where a cited page contributes language, evidence or structure. Its central finding: “Perplexity and Google cite more sources on average, while ChatGPT cites fewer sources but shows substantially higher average citation influence among fetched pages.”1 A short source list means competition for a handful of slots, and being fetched is not being cited.
The number nobody agrees on
Does Reddit really dominate ChatGPT citations?
Four published measurements put Reddit’s share of ChatGPT citations at 16.8%, 12.6%, 3.11% and 0.52% inside eleven months. They divide by different things.
Read the middle column before the right one. A share of the top 50 cited domains throws away the long tail before counting, so it always looks large. A share of answers containing a Reddit link counts answers, not citations. A share of every citation on every engine, from a corpus of more than four billion, is the strictest denominator and returns the smallest number.10
The bottom two rows are a change, not a denominator argument. Promptwatch recorded Reddit at 3.83% of ChatGPT citations between 18 July and 7 August 2026, then 0.52% between 14 and 17 August, an 86.4% relative decline reported by Search Engine Land and Search Engine Journal on 19 August.11 The cause is open: ChatGPT changed its background search behaviour on 8 August but citations held until 14 August, and the vendor calls the finding provisional.
So the honest claim is narrower than “Reddit dominates AI citations”. Reddit is one of the most-cited community domains in every measurement above, and its share on any one engine moves by multiples between versions. The leverage was never the percentage: “what do people actually use for this” is answered best by a document where several people already compared the options, usually a thread. See how community threads get selected and why third-party pages dominate.
Document shape
What does a passage ChatGPT can cite look like?
The dataset describes the profile directly: “High-influence pages tend to be longer, more structured, semantically aligned, and richer in extractable evidence such as definitions, numerical facts, comparisons, and procedural steps.”1 It describes pages that were already cited, measured on 18,151 fetched pages, and the authors frame the paper as descriptive, not as proof that adding a definition causes a citation.
What it licenses is a working shape: answer one question in one place, carry a number with its date and its denominator, and name the boundary where the claim stops holding. Google rules out the rest, stating that you do not need to create new machine readable files, AI text files or markup to appear in these features, and that there are “no additional technical requirements” beyond being indexed and snippet-eligible.6What a quotable passage looks like works through the form; length, schema and llms.txt prices the file-based tactics.
The method
How do you earn a mention in threads ChatGPT already cites?
Five steps, in this order. Almost everyone starts at step three, on a thread nothing has ever cited.
1
Start from cited URLs, not from subreddit size
Write the ten questions a buyer would actually type, run each on every engine you care about, and record every URL the answer cited. That list, usually near fifteen URLs, is your working set.
2
Read the thread before you read the subreddit
Check three things in order: the thread is still open to replies, its question is one you can answer with something specific, and the subreddit permits a reply from someone with a commercial interest.
3
Answer the question that was asked
A reply that gets quoted carries a constraint, a number and a boundary: what you measured, on what, and where it stops being true. The version that reads as positioning is removed by a moderator first.
4
Disclose the relationship where the community requires it
Where a subreddit or platform requires a commercial affiliation to be disclosed, disclosure is required, and the obligation does not weaken because part of the audience is a retrieval system.
5
Re-run the same prompts and watch the set move
Citation sets are not stable, so a thread that carried an answer in March may carry nothing in September. Re-run the fixed prompt set on a schedule, and stop spending on threads that dropped out.
Step one is what gets skipped, and skipping it is the most expensive mistake here. Picking communities by size produces a popularity ranking; the threads an engine retrieves are selected for matching a question, and the two lists overlap far less than anyone expects. A useful reply in a thread nothing has ever cited buys goodwill and no citations, and nothing tells you it failed.
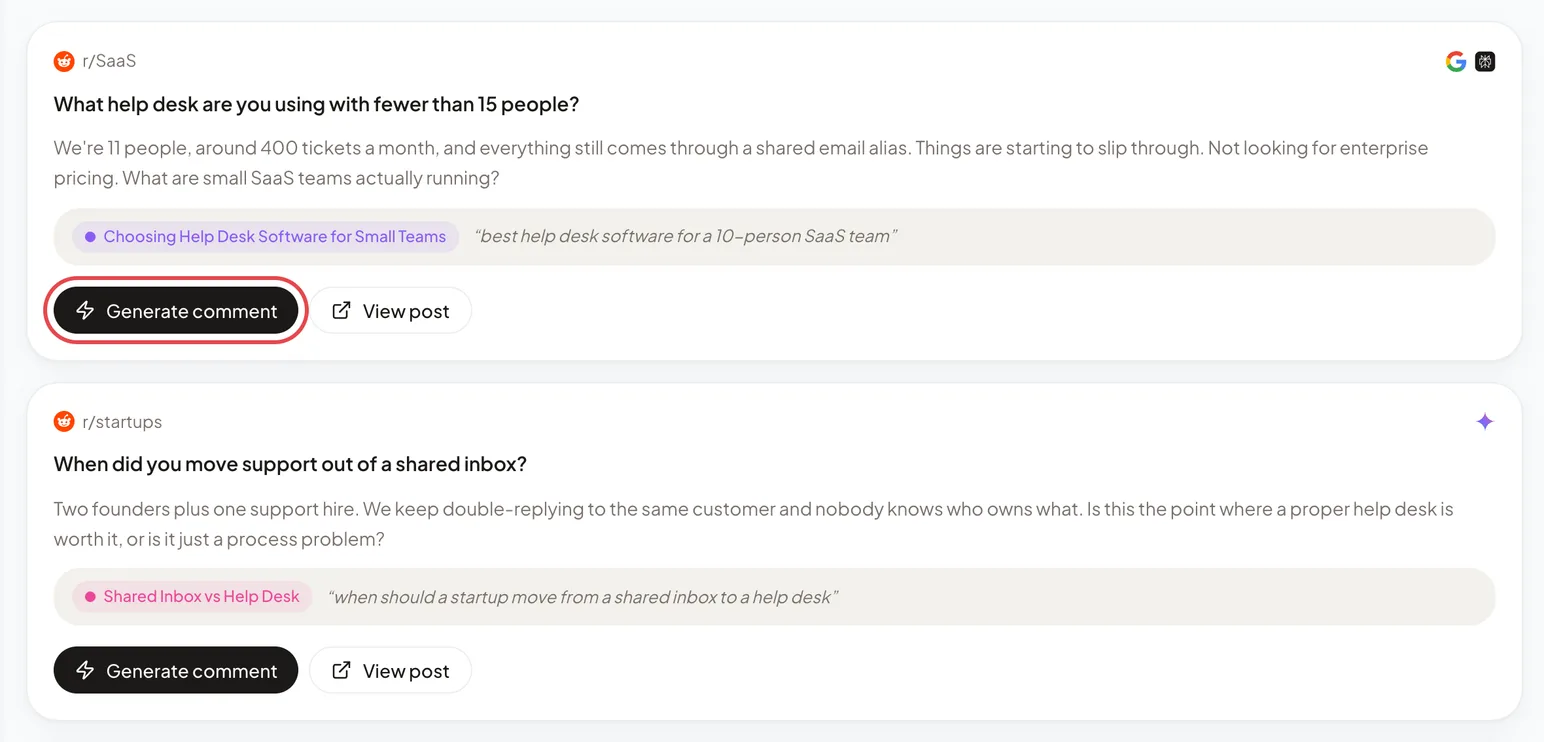
Steps one and two work by hand, with a spreadsheet of prompts and the URLs each answer cited; Bavior puts finding those threads, and drafting and approving replies, into one queue. Open Action Opportunities: each card is a thread an AI engine already cites, with its subreddit and the topic and prompt that surfaced it. Run the step-two check with View post before you press Generate comment.
Sample data from a demo workspace. Thread titles are illustrative, not real Reddit posts. The red box marks Generate comment, which starts a draft for your review, not a post.
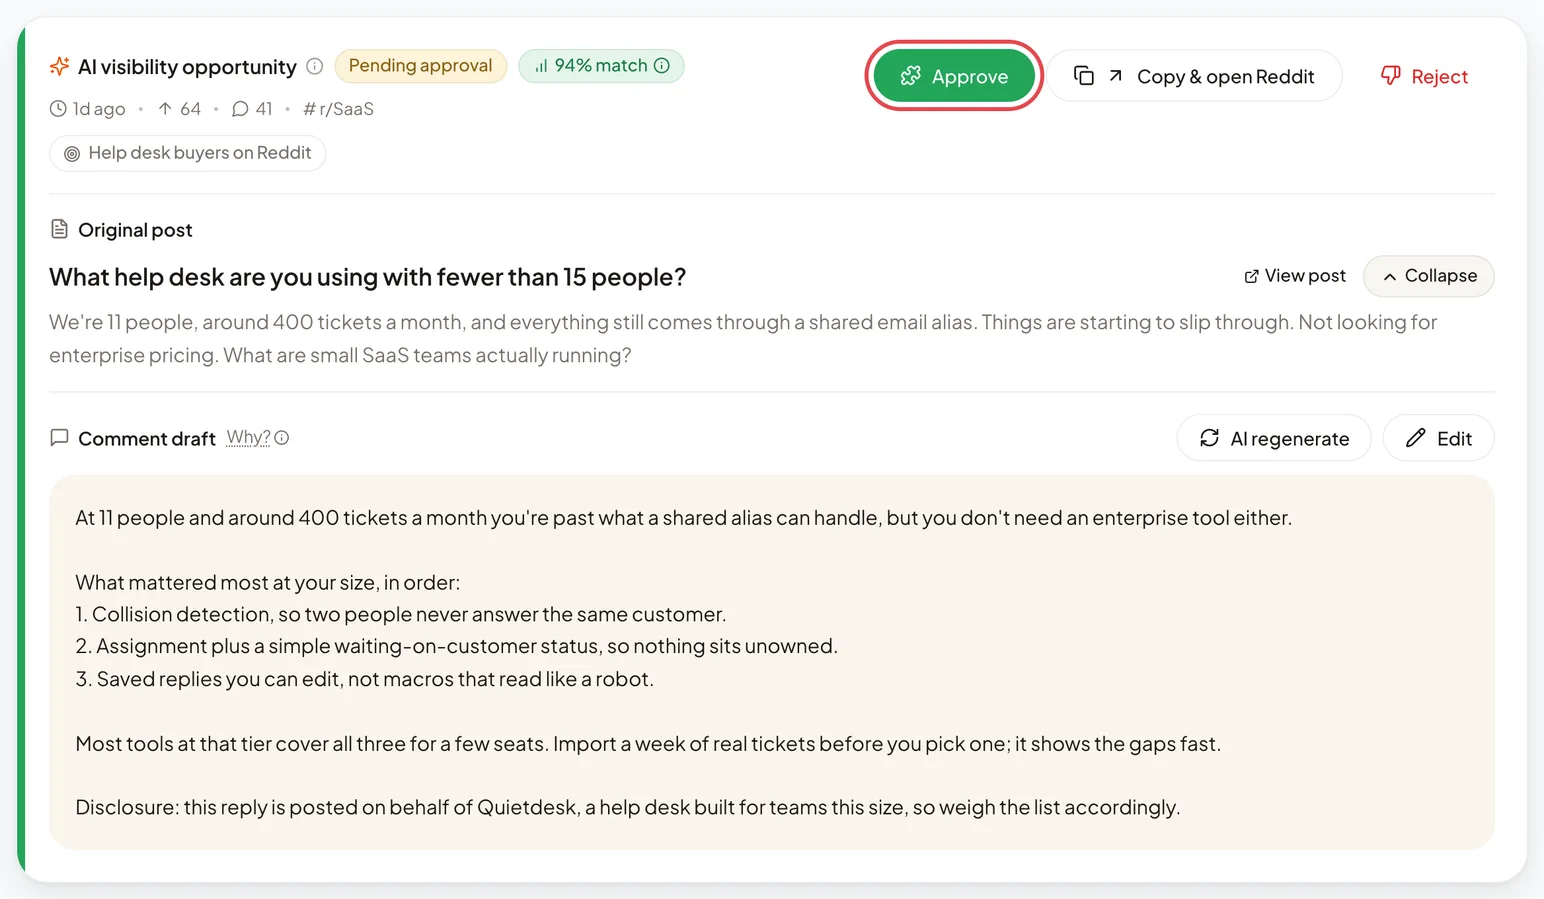
Drafts wait under Pending approval. Check each against steps three and four: does it answer within the poster’s limits, and does it disclose who it is posted for, as the subreddit requires? Edit until both hold. Approve hands it to a human operator posting from an account Bavior provides; Copy & open Reddit is for posting from your own.
Sample data from a demo workspace. Thread titles are illustrative, not real Reddit posts. The draft is for the same thread as the first card above; the red box marks Approve, and Bavior posts nothing without it.
One expectation to set honestly, because the popular version of this advice assumes it. An upvoted reply does not become a citation. It becomes part of a thread that may or may not be retrieved for a query you care about, and whether the engine issues that query is not yours to decide. No study this article could verify measures upvote count, comment depth or account age as an input to citation selection.
Query to citation
What happens between a question and a citation?
Four things, and you control one and a half. First the question is taken apart and searched repeatedly. Google documents a query fan-out technique, “issuing multiple related searches across subtopics and data sources”, and that a page must be indexed and snippet-eligible to appear as a supporting link, with “no additional technical requirements”.6 Yours here is only whether you are reachable, which is all of retrieval; the sub-queries are written by the engine, and query fan-out covers how far they drift.
Second, those results are cut to a candidate set and reordered. This stage has the strongest evidence and the least room for tricks: the one critical survey of the literature names “topical relevance and context position” as its most reproducible levers and warns that “generic heuristics transfer poorly”.3 See selection and reranking.
Third, the answer is written and then attributed, which is why a page can shape an answer without being named. See synthesis and attribution and the five-stage pipeline. Fourth, none of it holds still: the ACL 2026 comparison of organic search against five generative systems reports outputs that “vary across time and executions”.4
Tested and null
Which changes have been tested and found to do nothing?
Mostly the ones easiest to sell. C-SEO Bench, in the NeurIPS 2025 Datasets and Benchmarks track, tested white-hat conversational-SEO methods across 1,915 queries and more than 16,000 documents. Its result: “Out of 54 cases, we uncover only three where the ranking improvements are statistically significant.”2 That is most of what a GEO retainer buys, measured properly, coming out flat.
The 2023 to 2026 survey arrives from another direction. Already-retrieved content can causally change whether it is cited, and then the ceiling: “no reviewed technique shows a stable, longitudinal, cross-platform causal effect on organic discoverability or downstream behavior”.3 Editing a document already in the candidate set can matter; getting one into the set is where published evidence runs out. See content tactics that test null and rewrites that cost retrieval.
Google says a version of this itself: its “generative AI features on Google Search are rooted in our core Search ranking and quality systems”.7 There is no separate door, so spend less on re-editing the page you own and more on changing which documents exist about your category.
Diagnosis versus treatment
Why is monitoring alone not enough?
A monitor answers the easier of the two questions this work has: where you stand, which prompts mention you, which cite you, and which sources each answer pulled from. A diagnosis has never changed an outcome on its own.
The failure mode is a queue. Alerts land, the list of cited URLs grows, and the person who would read each thread, judge whether they can add anything real, draft it in a voice that fits and get it approved is the person whose week is already full. Threads age, and a question open in week one is answered by somebody else in week three.
What changes the list is the slow work it points at: replies that add something a reader could act on, in threads actually being retrieved, from accounts with a history, disclosed where required. See the off-site weekly workflow and program failure modes.
Measurement
How do you measure citation share without fooling yourself?
Fix the prompt set before you measure, and never change it in the same period you change the work. Report mention share, the proportion of runs that name your brand; citation share, the proportion of cited URLs that belong to you or describe you; and share of voice against the named alternatives. Do not report a rank, because there is no ranked list underneath.
Then repeat. The same ACL 2026 study found generative outputs vary across time and executions, which makes one run of one prompt uninformative.4 Several runs per prompt per period is the minimum that separates a change from noise. See metrics that hold up, statistical power and six things called visibility.
The honest limit of this article
Three things here are weaker than they look. The high-influence profile comes from a descriptive preprint on one dataset of 602 prompts, and a correlation between page features and citation is not evidence that adding those features causes citation. The claim that upvotes, comment depth or account age drive AI citations is unsupported by any study this article could verify, so nothing above rests on it. And every Reddit percentage quoted is a vendor measurement with its own denominator, one of them called provisional by the vendor.
Where a product fits, and where it does not
The free version takes an afternoon: run your ten most commercial questions on each engine you care about and record every cited URL. Bavior runs a fixed prompt set across five engines on a schedule and records which sources each answer cited, so the list stays current; where a cited source is a live discussion thread it drafts a reply in your voice, and nothing is published until you approve it, from Bavior’s aged accounts or your own account posting manually. It cannot make an engine cite you, does not buy placements, and posts nothing you have not read. Paid plans are from $99/mo.
Ahrefs, “Most cited domains in ChatGPT”, updated 2 Sep 2026; Brand Radar; mention share against the top 50 sources’ combined citations; reddit.com 16.8%, rank 1. Vendor measurement, unlinked under the /learn sourcing rule.
Semrush, “Reddit AI search visibility study”, 10 Nov 2025; 217,000 prompts, 248,000 Reddit URLs; Reddit in 12.6% of ChatGPT Search answers. Vendor, unlinked.
Profound with Reddit, 10 Nov 2025; 4 billion citations, Aug 2024 to Oct 2025; Reddit 3.11% of all citations, rank 2 in ChatGPT. Vendor, unlinked.
Promptwatch, via Danny Goodwin (Search Engine Land) and Matt G. Southern (Search Engine Journal), 19 Aug 2026; 3.83% to 0.52%, called provisional. Vendor, unlinked.
Nobody can give you a date, and anyone who does is selling something. Access is immediate once OAI-SearchBot is unblocked. After that it depends on a document existing that matches a question the engine decides to issue, and on citation sets that move between versions. Measure in quarters, and measure share.
Does blocking GPTBot stop me appearing in ChatGPT search?
No. OpenAI separates the jobs: GPTBot is for model training and OAI-SearchBot governs search results. The documentation states that sites opted out of OAI-SearchBot will not be shown in ChatGPT search answers, and that ChatGPT-User is not used to decide whether content may appear in Search. Check which one your robots.txt actually blocks.
Do upvotes make a Reddit thread more likely to be cited?
No study this article could verify measures upvote count, comment depth or account age as an input to citation selection. The evidence supports document shape and query match instead: a thread where several people compared options answers a comparison question better than a page about one option. Treat the upvote claim as unverified folklore.
Is Reddit still worth the effort if its ChatGPT citation share fell?
Decide it on fit, not on a vendor percentage. The published figures for the same domain in the same year range from 0.52% to 16.8% because each divides by something different, and one is labelled provisional. Run your own prompts, look at what is actually cited in your category, and spend where threads appear.
Bavior Editorial
The team that researches and maintains Bavior’s writing on Reddit marketing and AI search visibility. Every figure here is attributed to a named source with the date it was checked, and none of our links are affiliate links.
Found a number that looks wrong? Tell us and we will re-check it: support@bavior.com
ChatGPT is already citing somebody in your category. Find out who, and which threads it pulled from.